DigiEdze AI · AI Observability
Visibility into AI Systems for Proactive Risk Detection
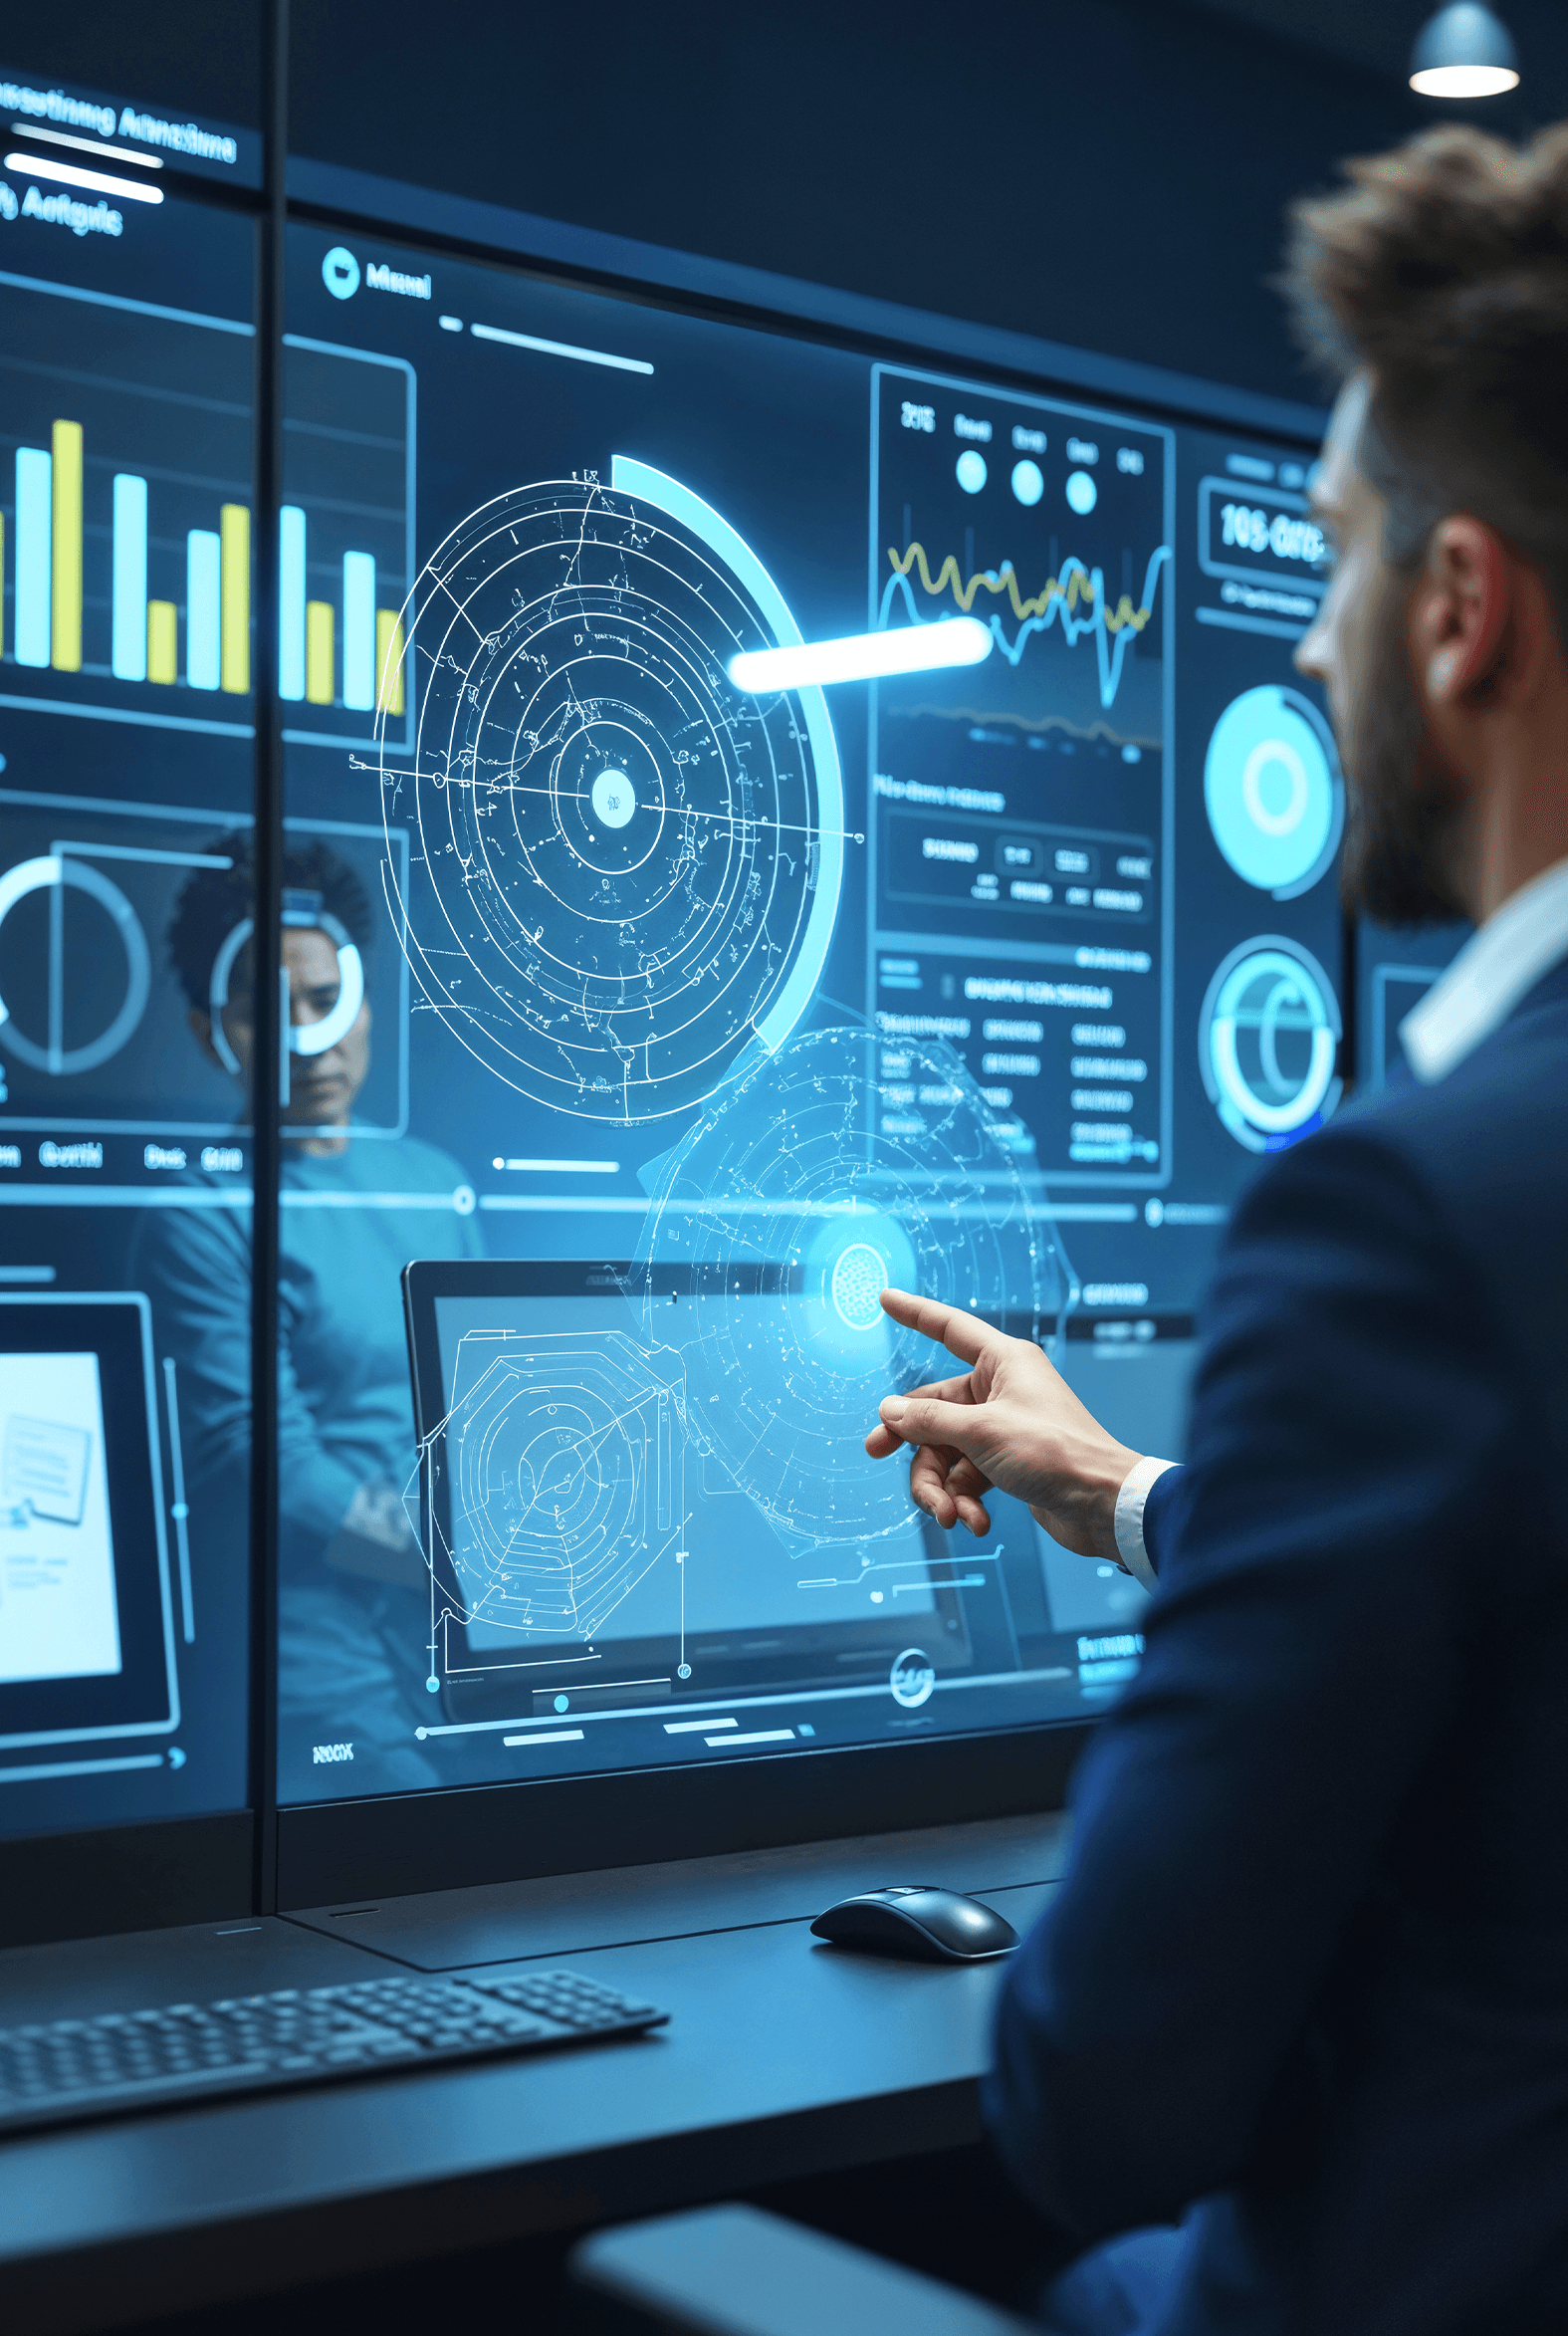
Traditional monitoring tells you the endpoint returned 200. AI observability tells you what was asked, what was retrieved, what the model reasoned, which tools it called, how long it took, what it cost and whether the answer was any good.
- prompts
- responses
- agents
- tools
- models
- latency
- failures
- tokens
- costs
- infrastructure
Reference architecture
- 06Instrumented applications & agents
- 05Trace pipeline with redaction
- 04Quality scoring join
- 03Cost attribution join
- 02Dashboards & alerting
- 01Retention & access control
The problem
Roadblocks to AI Observability
The service is healthy by every infrastructure metric while the answers are quietly wrong.
A quality complaint cannot be reproduced because the request context was never captured.
Cost, latency and quality are measured by different teams in different tools that never join up.
What we build
AI Observability Capability Grid
Full-fidelity tracing
Prompt, retrieved context, model call, tool invocations, response and evaluation in a single linked trace.
Retrieval observability
What was searched, what was returned, what was actually used — the fastest route to diagnosing bad answers.
Quality telemetry
Online scoring joined to the trace, so quality sits beside latency and cost rather than in a separate report.
Cost telemetry
Token, tool and GPU cost attributed per request, feature, agent and tenant.
Alerting on the right signals
Refusal-rate spikes, groundedness drops, tool-failure surges and cost anomalies — not just error rates.
Privacy-aware capture
Redaction and retention policy applied at capture, so observability does not create a new data-exposure surface.
How it works
Observability becomes a security and governance requirement for AI systems at production scale. We bring the technologies that make AI observability a continuous enterprise discipline.
Technology
- OpenTelemetry
- dZtrace
- Trace stores
- Evaluation pipelines
- Alerting platforms
Use Cases
Industrial Landscape
Technology
Regressions isolated to a prompt version within minutes rather than days.
BFSI
Retained traces provide evidence for internal audit and regulatory enquiry.
Telecom
Cost anomalies detected at the feature level before month-end.
Outcomes
What We Measure
Turning enterprise AI systems into observable assets transforms model behavior into actionable security protocols, strengthening proactive risk detection and incident investigation.
- Mean time to diagnose an AI defect
- Trace coverage of production traffic
- Cost visibility by owner
- Drift detection lead time
Questions
AI Observability, Answered Directly
Can existing APM tools cover AI workloads?
They cover the infrastructure half well. They do not carry prompt, retrieval, tool-trajectory, groundedness or token-cost dimensions, which is where AI failures actually live. In practice you extend APM with AI-specific tracing rather than replacing it.
Is capturing prompts a privacy risk?
It can be, which is why redaction happens at capture rather than at query, retention is bounded by policy, and access to trace data is controlled as tightly as access to the underlying source systems.
Choose your starting point
Where Are You Today?
Enterprise AI conversations stall when the entry point is wrong. Pick the sentence that matches your situation.
We have an idea.
→ AI STRATEGY
We have a POC.
→ AI PRODUCTIONIZATION
We have an AI application.
→ LLMOPS / AGENTOPS
We need autonomous workflows.
→ AGENTIC AI
Our AI is too expensive.
→ AI FINOPS
Our AI can't reach enterprise knowledge.
→ RAG & KNOWLEDGE
We can't send data to public AI.
→ SOVEREIGN AI
We need to run AI securely.
→ AI SECURITY
Drive AI Observability for Your Systems
Make your implementation effective by relying on proven expertise in building AI systems that drive your organization forward.
30 MINUTES WITH AN ARCHITECT · BRING YOUR HARDEST CONSTRAINT